
AI search optimization: appear in Google & ChatGPT
AI Overviews, AI Mode, ChatGPT, and Seznam AI answer directly in search. See how they pick sources, what not to pay for, and what to fix in 30 days.
We counted how many major Czech websites and e-shops block ChatGPT, Claude, and Perplexity. Many blocks never appear in robots.txt—the firewall or e-shop platform decides.
A quarter of the largest Czech websites keep out at least one AI bot. In our November 19, 2026 study, 208 of 819 reachable sites in the top 1,000 .cz domains (25.4%) and 284 of 1,223 e-shops (23.2%) block AI crawlers. Often only the firewall blocks them (lower estimate: a third to half of ChatGPT blocks), while robots.txt says nothing. If you want ChatGPT, Claude, or Perplexity to mention your business in answers, checking AI bots in robots.txt is not enough—your firewall or e-shop platform may decide.
AI bots crawl websites either to train models (GPTBot, ClaudeBot) or to answer queries with links (OAI-SearchBot, Claude-SearchBot, PerplexityBot). A robots.txt file (such as vasweb.cz/robots.txt) is a public sign on the door that well-behaved bots respect. A firewall (your host or Cloudflare) acts like a guard: it turns a bot away even when robots.txt says nothing.
We tested 1,000 .cz domains from the Tranco ranking (819 returned a page, which forms our percentage base) and separately 1,223 e-shops among 5,120 ranked .cz domains.
| What we found | Top 1,000 (819 sites) | E-shops (1,223) |
|---|---|---|
| Blocks at least one AI bot | 208 (25.4%) | 284 (23.2%) |
| GPTBot disallowed in robots.txt | 97 (11.8%) | 96 (7.8%) |
| GPTBot rejected by firewall | 83 (10.1%) | 137 (11.2%) |
| of which not disallowed in robots.txt | 49 | 82 |
| AI search bot disallowed in robots.txt | 41 (5.0%) | 27 (2.2%) |
| AI search bot rejected by firewall | 65 (7.9%) | 84 (6.9%) |
| llms.txt file | 85 (10.4%) | 294 (24.0%) |
Firewall figures are always a lower estimate: we count only explicit rejections where a normal browser and a control request passed in the same minute. Sites disallowing GPTBot in robots.txt include idnes.cz, mapy.cz, vinted.cz, denik.cz, aktualne.cz, lidovky.cz, irozhlas.cz, and hn.cz.
Heavily protected sites returned no page at all, so they are missing from the 819-site base. Across all 807 readable robots.txt files in the top 1,000, however, 127 (15.7%) disallow GPTBot. Protected sites block more often, so our headline numbers likely understate the total.
In the top 1,000 domains, 146 websites (of 819) block GPTBot: 63 in robots.txt only, 34 in both, and 49 (34%) at the firewall only (lower estimate). Among e-shops, 178 stores (of 1,223) block it, including 82 (46%) at the firewall only (lower estimate).
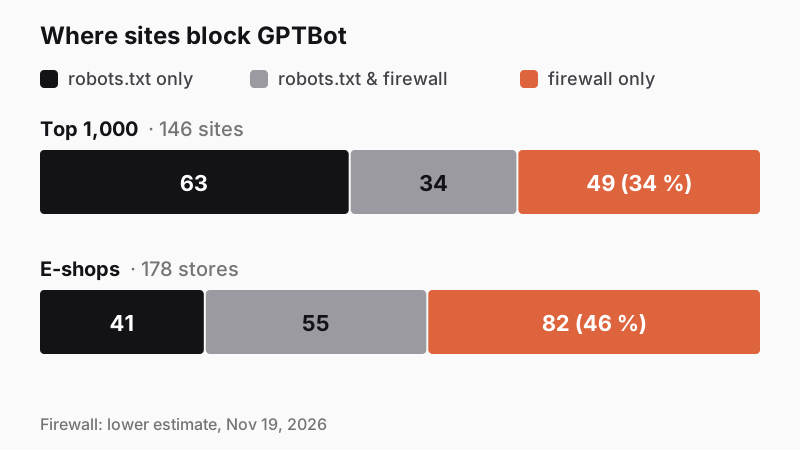
E-shops block GPTBot more often via firewall (137 of 1,223, lower estimate) than in robots.txt (96 of 1,223). Earlier studies read only robots.txt. Yet 191 of 819 large websites (23.3%) run through Cloudflare, which accounts for 55 of 83 firewall blocks of GPTBot on large sites and 79 of 137 on e-shops (lower estimates). Servers or hosts reject the rest.
On 29 top-1,000 sites and 42 e-shops, Cloudflare also inserts a "BEGIN Cloudflare Managed content" block into robots.txt that always disallows GPTBot. It does this when AI blocking is active in the zone settings—from the outside, we cannot tell if the owner turned it on knowingly.
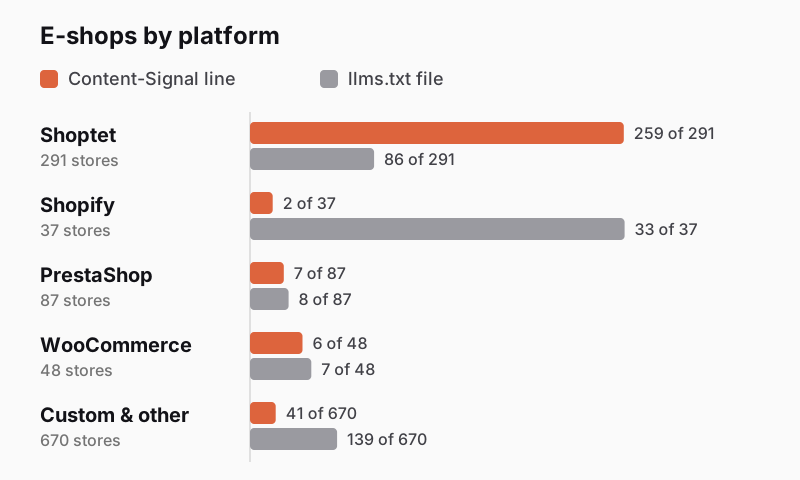
On e-shops, the platform—not the merchant—often controls robots.txt for AI bots. On Shoptet, 259 of 291 stores include Content-Signal: 232 disallow AI training (ai-train=no), and 190 set exactly "search=yes, ai-train=no".
Cloudflare's Content-Signal states whether AI may use content for search (search), answers (ai-input), or training (ai-train). Still, it is only a statement—just 4 of 291 Shoptet stores disallow GPTBot in robots.txt. Whether bots respect it is up to them.
Platforms similarly shape adoption of llms.txt, which summarizes site content for AI models. We found it on 294 of 1,223 e-shops (24.0%), compared with just 85 of 819 large websites (10.4%):
We discuss whether llms.txt pays off in our article on AI search.
Your platform or host also determines firewall rejections of GPTBot (lower estimate):
Running an e-shop on a hosted platform? Check robots.txt to see what it configured for you. We compare setup options in our e-shop platform comparison.
Only 41 of 819 large websites (5.0%) and 27 of 1,223 e-shops (2.2%) disallow search bots for ChatGPT, Claude, and Perplexity in robots.txt. At the firewall, however, at least 65 large websites (7.9%) and 84 e-shops (6.9%) reject OAI-SearchBot or PerplexityBot—a lower estimate in both cases.
Providers separate their bots like this:
In robots.txt, news and classifieds sites disallow search bots most often, including idnes.cz, denik.cz, zive.cz, ceskenoviny.cz, and sreality.cz. These are public lines in their robots.txt files.
Across the 819 reachable sites, firewalls most often reject ClaudeBot (92), GPTBot (83), PerplexityBot (59), and OAI-SearchBot (14)—each a lower estimate. Blanket AI blocking can therefore drop a site from cited answers even when the owner only meant to block training.
Today, 97 of the 1,000 Tranco .cz domains disallow GPTBot in robots.txt (11.8% of 819 reachable sites, 9.7% overall). In 2024, Apify found 21 using a different traffic-based ranking; Czech media outlet Lupa.cz reported "a mere three percent" on September 2, 2024. That is four to five times as many, though from different website lists. Apify also measured before Cloudflare's managed robots.txt, which now blocks 29 sites.
According to Czech media outlet Britské listy, Piperic scanned the entire Czech web in July 2026 and found any AI bot disallowed on 2.9% of 224,452 websites and 1.9% of 28,103 e-shops, excluding firewalls. Among the largest sites, 152 of 819 websites (18.6%) and 177 of 1,223 e-shops (14.5%) disallow at least one training bot in robots.txt. The two figures measure different things.
| Study | When | Websites | What it measured | Result |
|---|---|---|---|---|
| Apify (via Lupa.cz) | September 2024 | 1,000 most visited | robots.txt | GPTBot disallowed on 21 sites |
| Piperic (via Britské listy) | July 2026 | 224,452 active | robots.txt, llms.txt | 2.9% disallow an AI bot |
| Guap Media | Nov 19, 2026 | 819 of top 1,000 and 1,223 e-shops | robots.txt, llms.txt, firewall | GPTBot disallowed on 97 sites, AI bot blocked on 208 |
In a Studio Silex check (2026), 5 of 14 websites returned a 403 error; the authors attributed that to bot IP verification rather than AI blocking. We classify those as "indistinguishable", not as blocks.
You can check whether your website lets AI bots in within a few minutes in three steps:
curl -I -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot" https://www.vasweb.cz/
curl -I -A "Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot" https://www.vasweb.cz/Repeat this check after every domain move, host switch, or platform change—that is when settings shift without your knowledge. We cover what else to watch in Website redesign without losing traffic.
Decide on AI bot access in two steps based on whether you want to protect your content or get AI recommendations. The result should match your choice, not a default setting:
Learn how to appear in AI answers in our AI search article, and review the fundamentals in What you can do for your company's SEO. We can help improve your visibility through our marketing services.
We ran our scan on November 19, 2026, from a single computer in Prague on a residential IP address. Each website received at most eight sequential requests and we bypassed nothing—22,459 requests in under 15 minutes.
Website lists. Rankings come from Tranco list L5KW4 dated November 18, 2026 (a 30-day average from five sources). It measures domain popularity rather than traffic, and the top 1,000 .cz list includes technical domains. In total, 181 of 1,000 domains returned no page (130 rejected the browser, 51 did not respond) and are excluded from shares.
E-shops. From 5,120 .cz domains, we selected sites showing a platform signature and a cart, or a cart plus at least two of five sales signals. In a manual check of 40 sites, all were stores except at most two borderline cases. This includes hosts with carts, marketplaces, and ticket sellers; it misses non-.cz stores (.com, .eu), JavaScript-rendered sites, and sites rejecting browsers. "Custom and other" also covers platforms not recognized from HTML.
What we fetched. The homepage, robots.txt, and llms.txt as a browser, then the homepage five times as GPTBot, a control Googlebot, OAI-SearchBot, ClaudeBot, and PerplexityBot.
Robots.txt. Parsed under RFC 9309. We count only full-site disallows as blocks; partial disallows and sites closed to all bots including Google are tracked separately.
Firewall. Only explicit rejections (401, 403, 406, and 451) when both the browser and Googlebot passed in the same minute count as blocks—making this a lower estimate. Including 429 and 5xx codes (which can also indicate overload), 99 of 819 large websites and 193 of 1,223 e-shops reject GPTBot. Sites rejecting both GPTBot and Googlebot fall under "indistinguishable" (23 of 819 and 45 of 1,223) and are not counted as blocks.
What an outside scan cannot see:
Downloadable data. We publish only public files for all 1,900 sites in our share bases (rank, robots.txt verdicts for 22 AI bots and Googlebot, llms.txt, Content-Signal, and Cloudflare's managed block) in a CSV table. We do not publish per-site firewall data because external checks cannot verify how a site treats a real bot.
If you would like to review the AI bot settings on your website with us, tell us what you need.
Open vasweb.cz/robots.txt and look for "Disallow: /" under GPTBot and OAI-SearchBot. Check your firewall too (AI Crawler and Agent access policies in Cloudflare) and send a test request with the bot's header. In our study, robots.txt said nothing on 49 of the 146 large websites that keep GPTBot out.
Add "User-agent:" with the bot's name and "Disallow: /" beneath it in robots.txt. That blocks the site only for bots that follow the rules; a firewall is more reliable. Consider the bot type first: disallowing search bots removes you from cited answers, whereas disallowing training bots does not.
Both belong to OpenAI (ChatGPT). GPTBot collects data to train models, and disallowing it does not affect search. OAI-SearchBot handles search—if you disallow it, your site will not appear in ChatGPT answers.
Content-Signal states whether AI may use content for search (search), answers (ai-input), or training (ai-train). Setting "ai-train=no" declines training, though it does not block the bot. Most Shoptet e-shops had this line, yet only 4 of 291 disallowed GPTBot.
Handpicked topics for you
AI Overviews, AI Mode, ChatGPT, and Seznam AI answer directly in search. See how they pick sources, what not to pay for, and what to fix in 30 days.
Read our tips on boosting your search rankings and winning new customers for free
Most new online stores only need a hosted platform. Learn how to spot when you outgrow it and when custom e-commerce is an unnecessary expense.